
Slack chat.startStream: Streaming a Message, Timed and Tested
We streamed a bot reply into a Slack DM thread with chat.startStream, chat.appendStream and chat.stopStream, timed every call, screenshotted the thread mid-stream, and found how long an idle stream stays open.
chat.startStream creates a bot message that you then grow with chat.appendStream and finish with chat.stopStream, so a reply appears in Slack while your app or model is still writing it. On 3 October 2026 we ran all three methods with a bot token in a DM thread of our own test workspace. The app was a plain bot with the chat:write scope and no agent feature turned on, and streaming worked. We timed each call, took screenshots mid-stream, triggered every error we could, and measured how long a stream stays open when you stop appending.
The script we ran
import sys, json, time
from lab import raw   # our helper: POSTs JSON to https://slack.com/api/<method> with the bot token
DM = "D0C6CRJSZK8"; THREAD = sys.argv[2]
def show(label, r, t0=None):
    keep = {k: r.get(k) for k in ("ok", "ts", "error", "warning", "response_metadata") if r.get(k) is not None}
    print(label.ljust(30), json.dumps(keep), flush=True)
    return r
step = sys.argv[1]
if step == "errors":
    show("start, no thread_ts", raw("chat.startStream", {"channel": DM, "markdown_text": "hi"}))
    show("start, thread_ts=0", raw("chat.startStream", {"channel": DM, "thread_ts": "0", "markdown_text": "hi"}))
    show("start, bad thread_ts", raw("chat.startStream", {"channel": DM, "thread_ts": "123.456", "markdown_text": "hi"}))
if step == "run":
    gap = float(sys.argv[3]); n = int(sys.argv[4])
    t0 = time.time()
    r = show("startStream", raw("chat.startStream", {"channel": DM, "thread_ts": THREAD, "markdown_text": "**Release 4.53 summary**\n"}))
    ts = r["ts"]; json.dump({"ts": ts}, open("stream616.json", "w"))
    lat = []
    for i in range(1, n + 1):
        a = time.time()
        r = raw("chat.appendStream", {"channel": DM, "ts": ts, "markdown_text": f"chunk {i:02d} "})
        lat.append(int((time.time() - a) * 1000))
        if not r.get("ok"): show(f"append {i}", r)
        time.sleep(gap)
    print("appendStream x%d: ms min/median/max = %d/%d/%d" % (n, min(lat), sorted(lat)[len(lat)//2], max(lat)), flush=True)
    r = show("stopStream", raw("chat.stopStream", {"channel": DM, "ts": ts, "markdown_text": "\nDone."}))
    print("stored text:", repr((r.get("message") or {}).get("text", "")))
    print("total seconds: %.1f" % (time.time() - t0))
    show("append after stop", raw("chat.appendStream", {"channel": DM, "ts": ts, "markdown_text": "late"}))
    show("stop again", raw("chat.stopStream", {"channel": DM, "ts": ts}))
THREAD is the ts of a message the user sent in the DM. We ran it twice: 20 chunks with 0.2 seconds between appends, then 20 chunks with 1 second between them so we could take screenshots.
What each call returned
The run with 1 second gaps:
startStream                    {"ok": true, "ts": "1790989878.185369"}
appendStream x20: ms min/median/max = 282/311/847
stopStream                     {"ok": true, "ts": "1790989878.185369"}
stored text: '*Release 4.53 summary*\nchunk 01 chunk 02 chunk 03 chunk 04 chunk 05 chunk 06 chunk 07 chunk 08 chunk 09 chunk 10 chunk 11 chunk 12 chunk 13 chunk 14 chunk 15 chunk 16 chunk 17 chunk 18 chunk 19 chunk 20\nDone.'
total seconds: 28.3
append after stop              {"ok": false, "error": "message_not_in_streaming_state"}
stop again                     {"ok": false, "error": "message_not_in_streaming_state"}
The run with 0.2 second gaps returned the same shape: every append ok, latency 283/299/880 ms, 11.9 seconds in total. Each chat.appendStream is a full round trip of about 300 ms, so sending appends one after another caps you at about three per second. If your model produces tokens faster, buffer them and append every few hundred milliseconds.
The stored text is the whole message: **bold** from markdown_text was saved as Slack's *bold*, and the chunks are joined with no extra spaces.
Never appear "away" on Slack again
Cloud-based. No downloads. Works 24/7 even when your laptop is off.
What the user sees while it streams
Slack types the text out letter by letter, so the screen trails the API. Four seconds into the 1 second run, about three appends had returned, but the thread showed only "Release 4.53 sum". Later frames caught up to within a chunk:
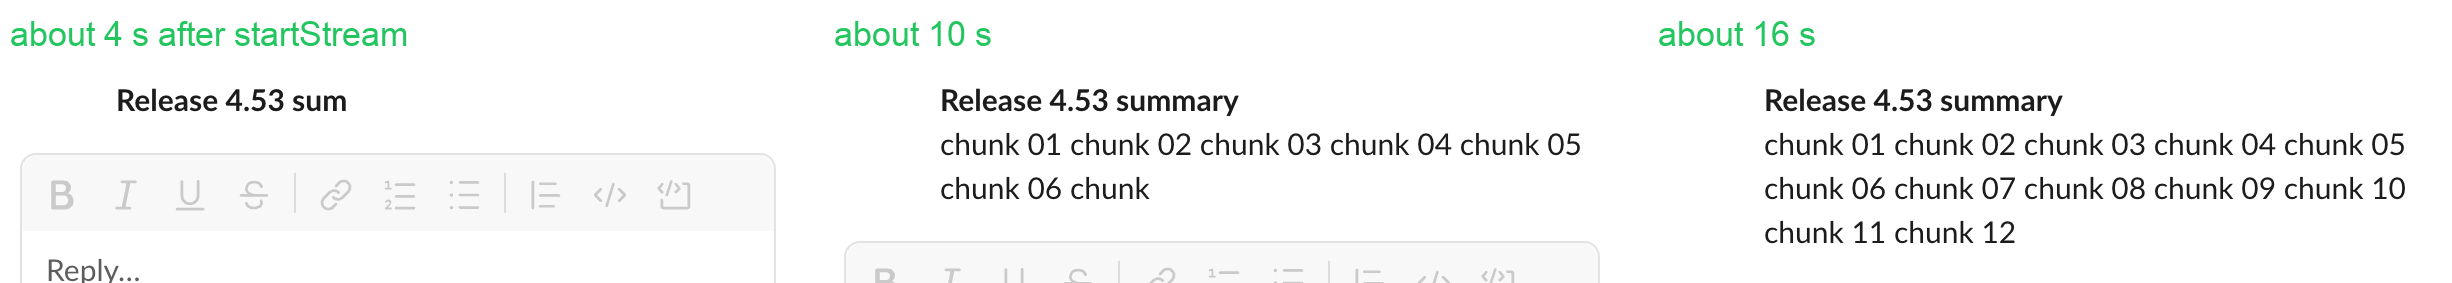
When the stream stopped, the message looked like any other bot reply, with "Done." on its own line. Nothing marks it as streamed.
Errors we hit
| Call | Response |
|---|---|
chat.startStream in a DM with no thread_ts | invalid_thread_ts |
chat.startStream with thread_ts: "0" | invalid_thread_ts |
chat.startStream with a made-up thread_ts (123.456) | invalid_thread_ts |
chat.appendStream after chat.stopStream | message_not_in_streaming_state |
chat.stopStream a second time | message_not_in_streaming_state |
So in a DM or a normal channel a stream must be a thread reply. The reference says a top-level stream works only where the whole channel is one session, such as Slack Code. We also started six streams in the same thread at once, and Slack accepted all six.
How long an idle stream stays open
We started streams in one thread and sent each a single chat.appendStream after a different wait, with no traffic in between:
| Wait before the append | Result |
|---|---|
| 61 s | ok |
| 180 s | ok |
| 301 s | ok |
| 311 s | message_not_in_streaming_state |
| 322, 331, 341, 352 s | message_not_in_streaming_state |
| 361 s and 601 s | message_not_in_streaming_state |
So an idle stream closes on its own after about 5 minutes, somewhere between 301 and 311 seconds in our runs. Nothing told us it had closed until the next append failed. conversations.replies then showed each timed-out message with the text it had and "streaming_state": "completed", the same value as a stream we stopped ourselves. If your model can pause that long (a slow tool call, a rate limit), send a small append before then, or stop the stream and start a new one, and treat message_not_in_streaming_state as "closed", not as a failure to retry.
If you show a status line before the first chunk, our assistant.threads.setStatus test covers how long that line lasts. To show the steps an agent took, the plan and task card blocks are the static version.
Stop Jiggling Your Mouse.
Join hundreds of remote workers who never worry about their Slack status. Set it up once, stay green forever.
Related Articles
Slack Plan and Task Card Blocks: Every Status, Update and Limit Tested
We posted a plan block with tasks in all four statuses and standalone task cards from a bot, updated them with chat.update, and probed the limits. pending works only inside a plan, and titles have no length limit we could find.
Slack views.update and views.push: Stack Limit, hash_conflict and response_action, Tested
We opened a Slack modal, pushed views until Slack refused, updated the top view with a current and a stale hash, and answered view_submission with every response_action. Every response and what the user saw.
Slack Block Kit Select Menus: Static, Multi, Users and External, Tested
We posted all four common select menus from a Socket Mode app, picked a value in each, logged the block_actions payloads, and timed an external_select options handler from 0 to 5 seconds. Past 3 seconds Slack silently shows the old results.